arXiv publishes hundreds of new computer-science papers every weekday, spread across category mailing lists nobody has time to read cover-to-cover. We wired the daily listings into a single digest page — every new submission across eight categories, deduplicated and filterable.
arXiv Digest — today’s papers →
Today’s firehose, measured
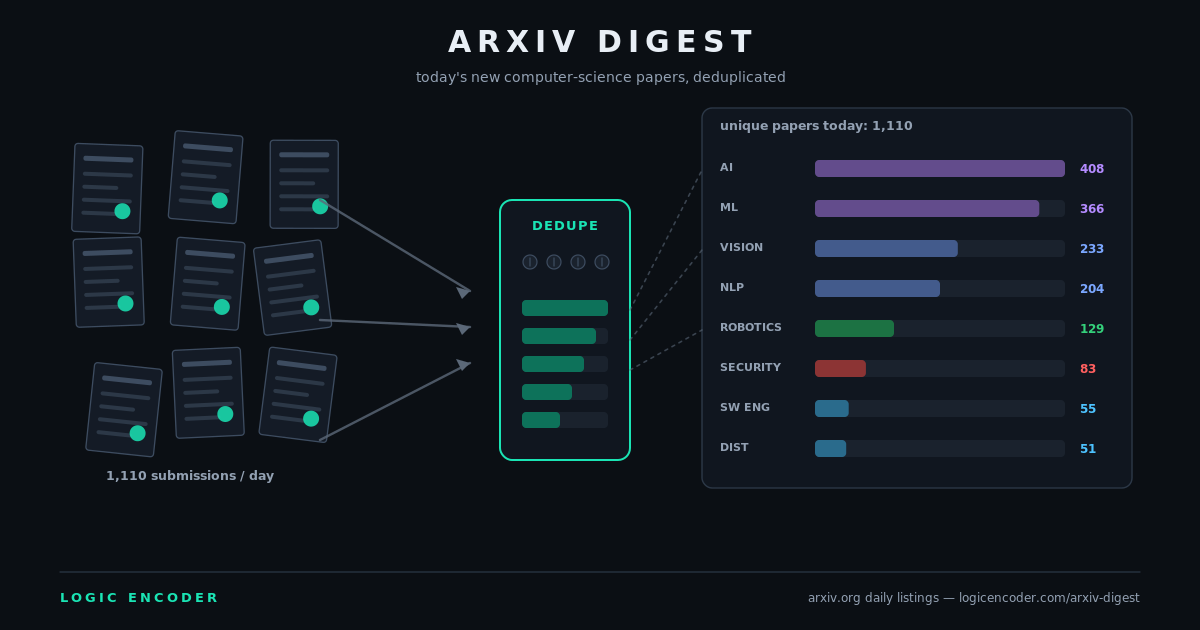
At the time of writing, 1,110 unique papers were submitted today across the eight categories we watch — AI, NLP, vision, ML, security, software engineering, distributed systems and robotics. That is one day. Cross-listed papers (a security paper also filed under ML, say) are merged into one row with all their tags, so the count reflects actual papers, not list appearances.
The category split itself is a data point: AI leads with 408 filings, ML 366, vision 233, NLP 204, robotics 129, security 83, software engineering 55 and distributed systems 51. A quick scan of today’s titles shows where research attention sits: agent harnesses and chain-of-thought monitoring, world models, safety filtering for robot control, and backdoor attacks on latent models.
How the digest works
Our collector reads the public daily listing for each watched category a few times a day, extracts each paper’s ID, title, authors and subject classifications, and merges entries that appear under multiple categories. The board sorts newest-first, filters by category, and every ID links straight to the abstract on arXiv. Papers stay listed for two days — enough that checking once a day catches everything.
One engineering note worth sharing honestly: arXiv’s official export API rate-limits aggressively, so we read the same public listing pages the site’s own UI uses — identical data, fewer headaches. The first version also silently showed only the top 50 entries per category; pulling the full listing more than doubled the real count. The sort of thing you only learn by measuring.
Why bother
For anyone tracking research — which model families are hot, which attack classes are getting attention, where the citations of tomorrow are being born — a deduplicated daily list beats eight email digests. And because we keep every day’s listing, the archive becomes a dataset: “security submissions per week this quarter” or “when did agent-framework papers spike” become answerable from our own numbers.